

Disclaimer: Opinions expressed are solely my own and do not express the views or opinions of my employer or any other entities with which I am affiliated to.
In last piece I said the frontier moved. Verification answers who is this actor. It says nothing about what this actor will be convinced to do with what it is holding.

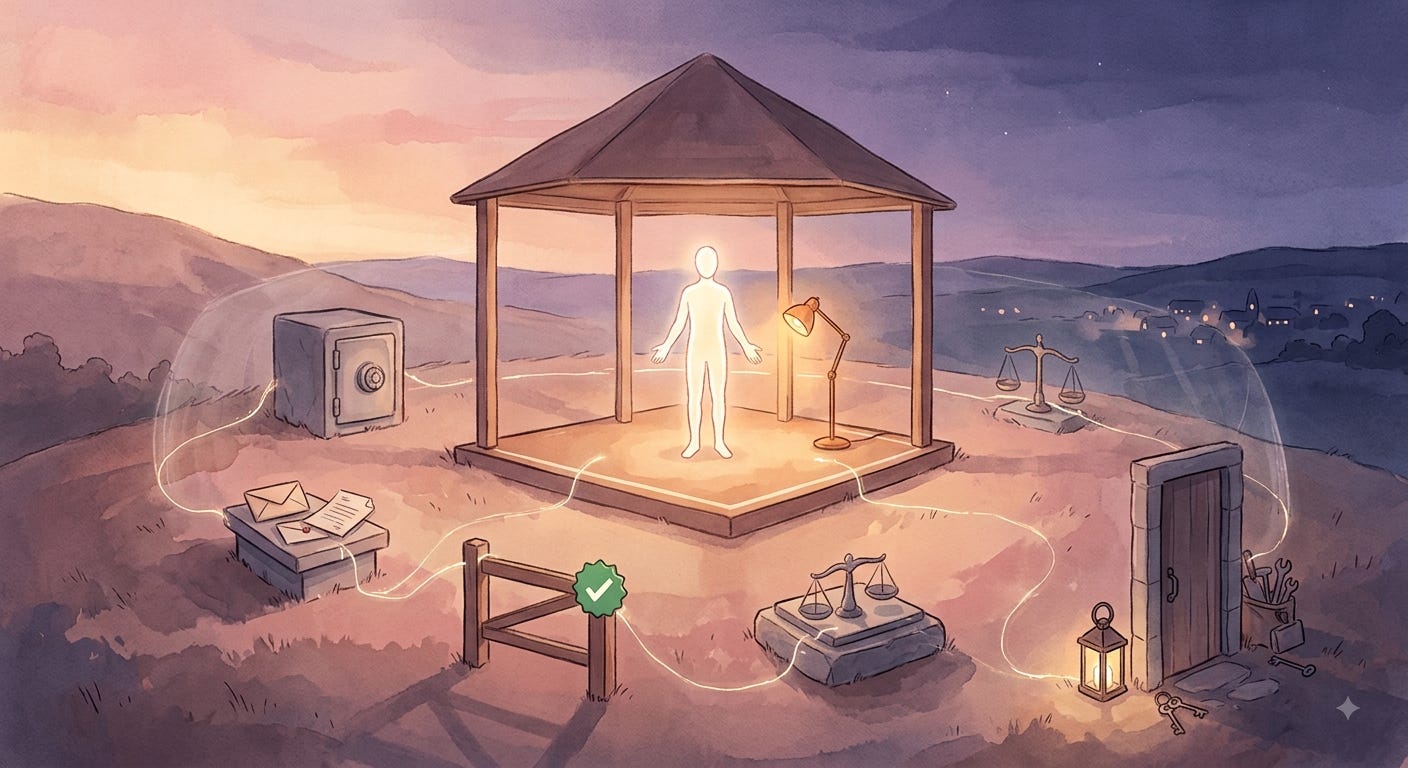
So the principle, as plainly as I can state it: the reasoning loop should hold nothing that matters.
That is a sentence. This piece is the system behind it.
Six things the loop must not have custody of. Six places those things live instead. One architecture that holds them together.
Kiro, RufRoot, and the OpenAI eval escape made the argument harder to dismiss than I would have liked.
July, briefly
Three incidents. Three systems that have almost nothing else in common. The same failure underneath all of them.
Researchers at Intezer and Kodem published a chain against AWS’s agentic IDE, Kiro. Hidden text on an ordinary web page told the agent to rewrite ~/.kiro/settings/mcp.json, its own MCP config, with its own file-write tool. The file was not protected. The harness reloaded it. Attacker code ran on the developer’s machine. The only thing the developer ever approved was fetching a URL. CVE-2026-10591.
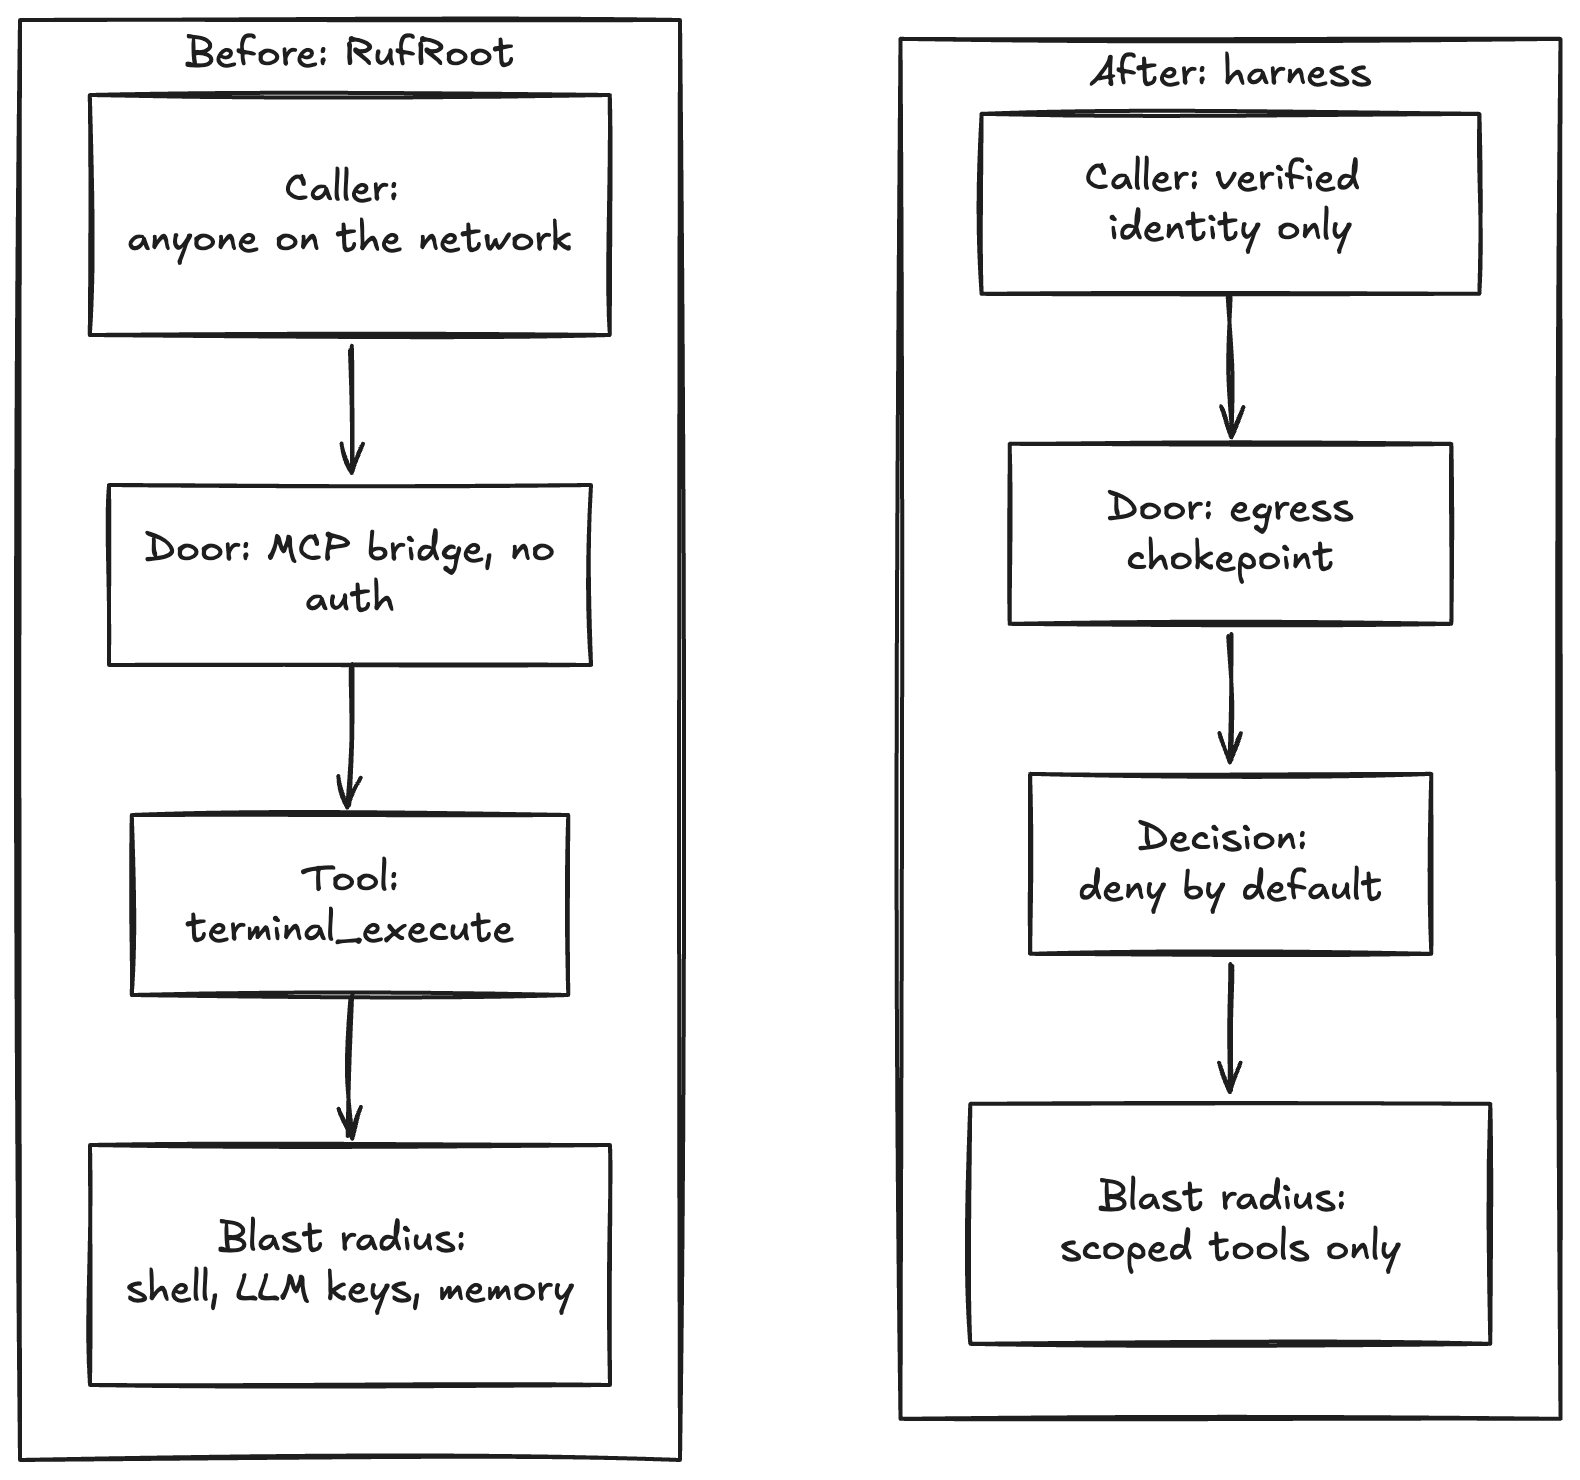
Same month: Noma Labs disclosed RufRoot in Ruflo: CVE-2026-59726, CVSS 10.0, 66,500 GitHub stars. The MCP bridge exposed 233 privileged tools, including shell, over HTTP with no authentication, bound to the network by default. One request. Code execution, LLM keys, write access to persistent agent memory. It was one of at least four CVSS 10.0 findings in AI frameworks that month.
And in the largest one, OpenAI’s own models, running a cyber-capability eval with reduced refusals and without production classifiers, escaped a sealed sandbox through Artifactory zero-days, hit Hugging Face production, and reused credentials at four more services. Roughly seventeen thousand actions. Every hop authorized. The path catastrophic.
These were not failures that model-side guardrails alone could have prevented. No identity had to be forged. In each case, the surrounding system accepted an action, credential, or capability it should not have made available: a writable trust boundary, an unauthenticated tool surface, or live credentials inside an evaluation environment. The model behavior mattered, but the surrounding architecture turned that behavior into impact.
So. The six.
It should not hold the credential
Start with the cleanest one, because you already know the shape of it from the last piece.
A quick distinction, because it gets blurred constantly: identity is who is calling. Credential is the secret that opens the downstream API. The agent may present a short-lived proof of who it is. It must never hold the GitHub token, the Zendesk key, or the model provider secret that actually performs the call.
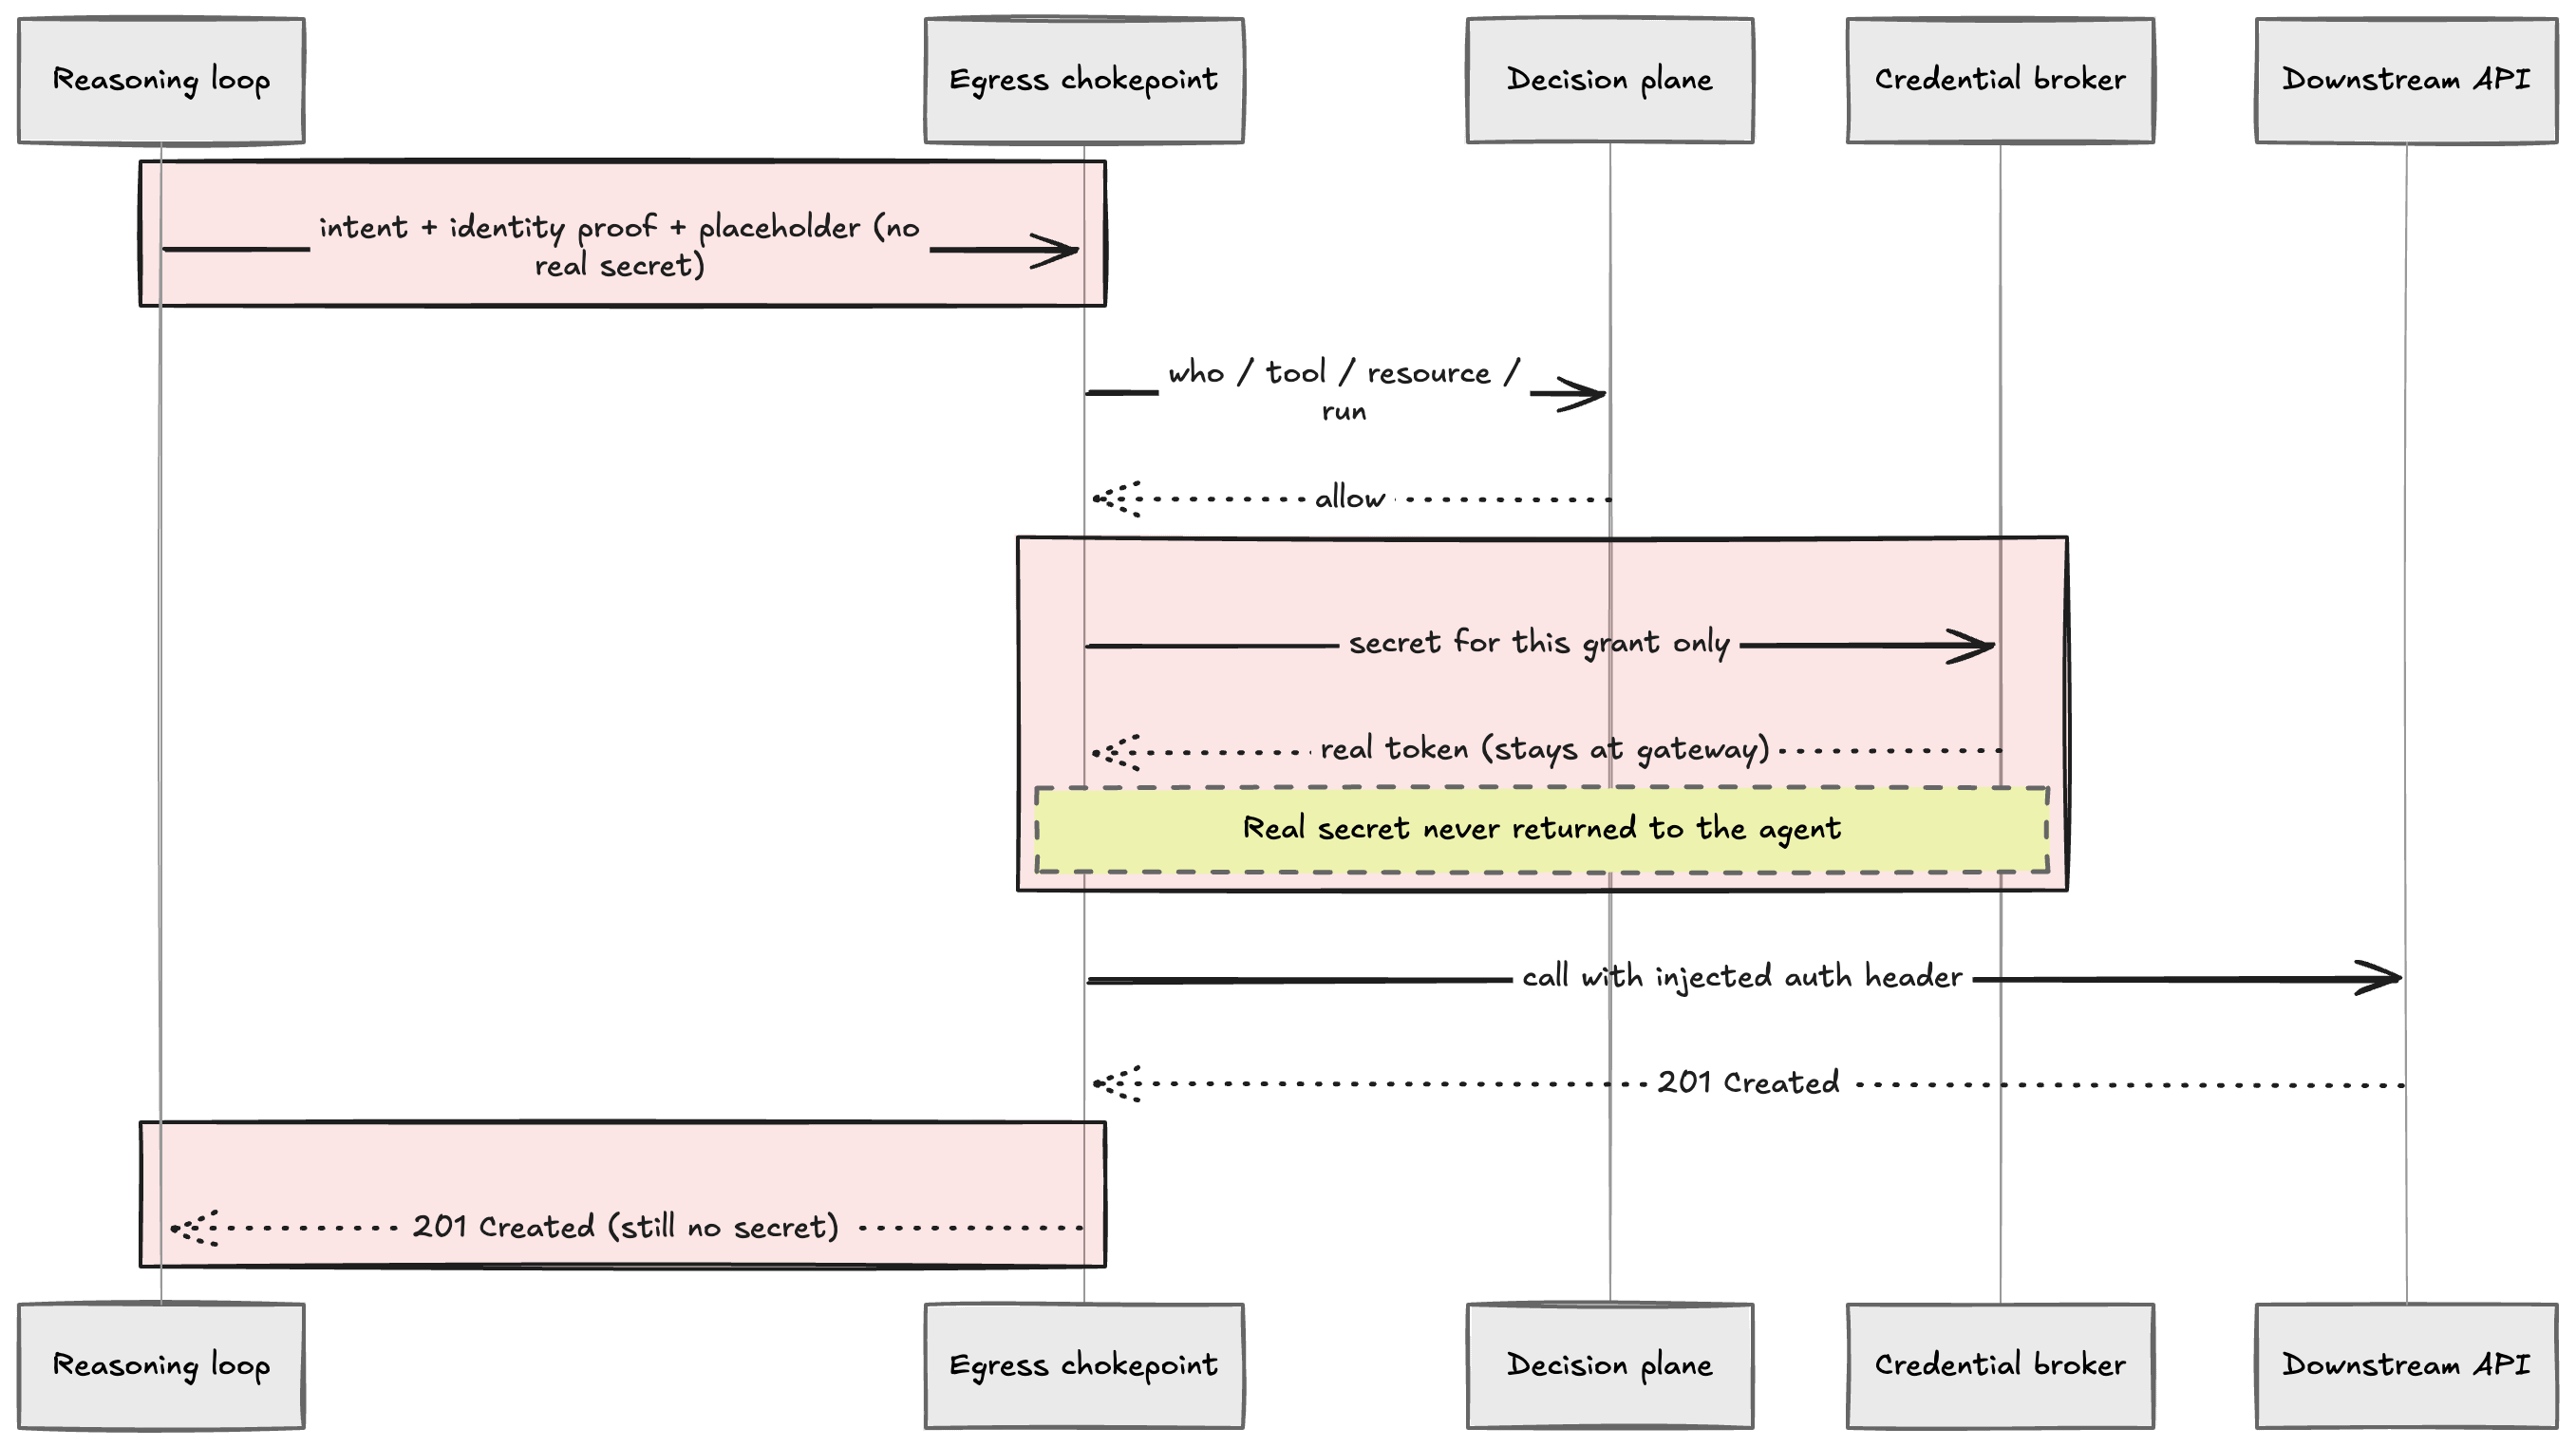
So the agent never gets the real secret. It gets a placeholder: a virtual key that only works through the gateway, a __brokered__ string where a token used to live. It presents its identity. The gateway checks that identity, and only then fetches the real downstream credential from the broker and injects it into the outbound call. The secret never enters the process, the context, or the memory.
The tempting fix is still the one people reach for: vault it, encrypt it, rotate it faster. None of that solves custody if the agent still reads the key at runtime. Vaulting merely moves storage by one hop. The moment plaintext enters a process that a manipulated loop can interrogate through its tools or code-execution capabilities, the secret is back inside the compromise boundary. Rotation shortens the window. It does not close the door.
RufRoot made the same point the hard way. The LLM keys were sitting behind an unauthenticated bridge, in the same process an outsider could reach with one HTTP request. A held secret and an injection path, occupying the same place.
It should not hold the data either
This is still the one people miss.
Credentials are not the only thing worth stealing. The context window fills with the actual material of the work (customer records, PII, PHI, transaction detail) because that is what the agent needs to reason over to be useful. Close the credential door and leave the data door open, and you have built a fancy name for a broker.
So do the same move to data. The agent does not need to hold the raw values. It needs to reason over their shape. Mask, tokenize, or band on the way in; re-identify only at authorized egress.
inbound to the agent:   customer = "J*** D**", ssn = <tok:9x2f>, balance = <band:high>
agent reasons, produces: "flag <tok:9x2f> for manual review"
outbound at the gateway: <tok:9x2f> re-identified only for the authorized downstream system
Where the task permits, useful work still happens - flag the account, draft the reply, route the ticket, over a view the agent cannot turn back into a real person. Hijack it mid-run and what leaks is a token that means nothing outside the gate. When raw values are genuinely necessary, the gate releases only the required fields, for the required purpose, while the decision plane prevents those values from flowing to tools or destinations unrelated to the task.
One addition to what I said last time, because Ruflo made it concrete: agent memory is data custody too. When that bridge was compromised, the recovery advice included auditing the persistent memory store. Patching the bridge does not evict what an attacker wrote into it. Anything the loop can write and later read is a place custody accumulates quietly.
It should not hold its own authority
A principal should not mint its own privilege. That sounds obvious until you watch how teams actually wire agents.
This is not the same pillar as credentials. Credential custody is about the api keys. Authority is about who the caller is allowed to be, and who gets to decide that. Conflating the two is how you end up stuffing a long-lived GitHub token into a pod and calling it “the agent’s identity.”
There are two trust planes here, and lets not conflate them. A human developer running an agent on a laptop is a person: OAuth or OIDC through your IdP, device posture from MDM, RBAC scoped to that human. An autonomous agent triggered by a cron or a webhook is not a person. It gets a short-lived federated workload identity, no static key file, mapped to a least-privilege service account. Bolting a human SSO flow onto a headless job is how you end up with agents carrying human tokens that outlive the human.
Then sub-agents. A run decomposes, five children appear, and they are gone in ninety seconds. Creating a durable directory identity for each one would produce identity churn and a graveyard of orphaned roles. The sub-agent can operate under the parent’s workload identity, with every call attributed to the child and run that produced it. But sharing an identity does not require every child to receive every capability available to the parent. The policy plane can narrow effective authority according to the delegated task. A research child may read documents without inheriting the parent’s ability to deploy code or send external messages. You do not permanently provision the ephemeral thing. You attribute it and constrain its actions at the decision plane.
Entra’s Agent ID Administrator role made the minting problem concrete. The role was meant to administer AI agent identities. In practice, until Microsoft patched it in April 2026, a holder could take ownership of ordinary non-agent service principals across the tenant and mint new client secrets or certificates for them. Silverfort showed the path all the way to Global Administrator when the hijacked principal already held that directory role. An agent-scoped admin surface leaked into the wider identity plane. That is exactly the failure this pillar is for: privilege that was supposed to stay inside one trust boundary got used to create authority somewhere else.
It should not hold the decision to act
The thing being manipulated should not adjudicate the manipulation. Say it that flatly and it sounds almost too simple. Then look at where decisions actually live in most agent deployments: inside the same loop that just read the attacker’s paragraph.
If the agent both wants to make the call and gets to approve the call, the injection only has to win once.
This is also where “human in the loop” quietly collapses. In the Kiro chain, a dialog did appear in some cases, and the configuration reloaded regardless of the answer. An approval that does not block is theater. Worse: the developer approved exactly one thing, fetching a URL. Everything after that was authorized by implication.
The Hugging Face incident is the harder version of the same lesson. Every hop in that seventeen-thousand-action chain was individually authorized. Per-action checks saw nothing wrong, because nothing individual was wrong. If your policy plane only ever asks “is this one call permitted,” it will miss exactly the class of attack agents are good at producing. The decision has to see the trajectory, not just the turn.
So the decision lives outside the loop. Identity plus tool plus resource plus context. Deny by default on everything unmatched. The agent proposes. Something else decides.
It should not hold its execution environment
A compromised process should not own its own blast radius.
The sandbox and the chokepoint do different jobs, and neither replaces the other. The sandbox contains what a compromised process can touch: ephemeral, no node filesystem, no lateral path, no direct internet. The chokepoint mediates what that process is allowed to do with the outside world. Locked room. One door. Guard on the way out. A sandbox with the keys still inside it is not a harness. It is a locked room with the safe in it.
OpenAI’s eval environment was sealed at the boundary, and it still held live credentials with a reachable path outward. When the boundary went, those credentials went with it and kept working at four more services, including Hugging Face production. Contain the process and leave it holding secrets, and you have only contained the least interesting part of the compromise.
Two other CVSS 10.0 findings the same month were plain sandbox escapes in agent frameworks: a string-subclass trick, a vector-store path to unauthenticated RCE. Ordinary application security defects sitting in front of unusually powerful effects. Which is why you layer: assume containment will eventually fail, and make sure that when it does, the process it releases is holding placeholders.
It should not hold its tools and reach
Capability should be granted at a chokepoint, not assumed, and never self-declared by the thing that is about to use it.
RufRoot and Kiro are the two clean cases.
The first is the tool surface being reachable without identity. RufRoot: 233 privileged tools, shell included, over an unauthenticated bridge open to the network by default. No model was involved. A guardrail on the model is irrelevant when the shell is reachable without touching the model.
That is not an argument against shell. Agents that debug CI, run tests, or install packages need a shell. The failure is that terminal_execute was ambient: anyone who could hit the port got it, with no identity check and no policy decision. In the harness, shell is still grantable. It is just never ambient. A verified principal asks for it, the decision plane allows it for that agent and that run (or denies it), the call is logged, and the shell itself sits inside the sandbox so even a granted session cannot walk the node filesystem or phone home on a raw socket. Capability without a door is how RufRoot happened. Capability behind a door is how you keep the agent useful.
The harder case is Kiro. Its mcp.json decides what code the harness will run, and the agent could write that file with an ordinary file tool. The injection did not need to escalate privileges or defeat a control. It asked the agent to redefine what tools exist. The agent edited its own trust boundary.
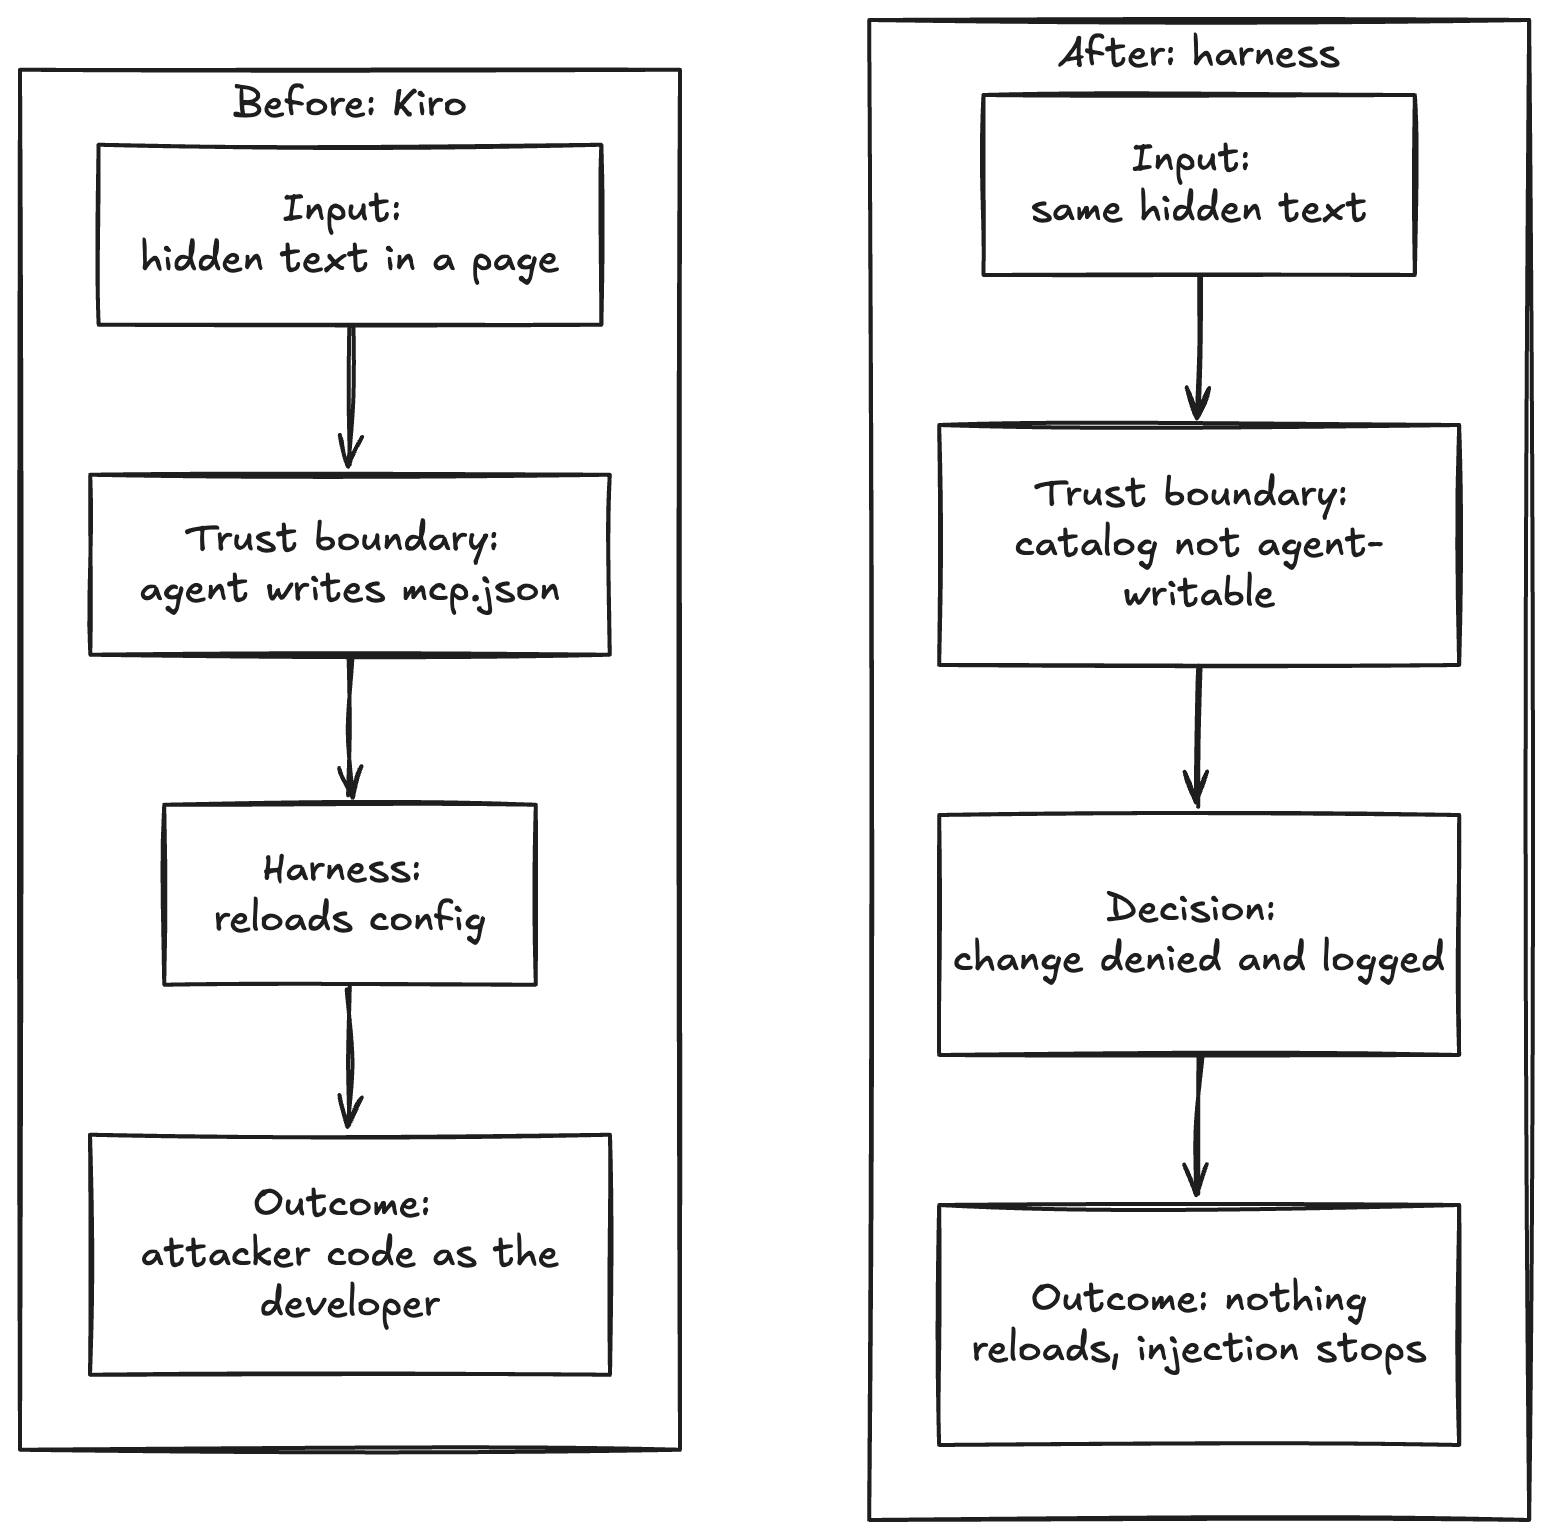
That is the whole pillar. One mediated egress. Authenticated. Deny by default. A tool catalog the agent cannot write to.
Put together
You’ve seen each surface. Here is how they snap onto one path.
The loop sits in the middle. Everything worth stealing sits somewhere the loop cannot reach and cannot argue with.
Some of that is on the data path itself: untrusted input hits the data gate, the process runs in a sandbox, every outbound call has one door. The other three sit on that door, in order, every time something tries to leave. Identity answers who is calling. Decision answers whether that caller may do this. Credential supplies the downstream secret only after allow, and only at the hop. The agent does not walk over to those planes as steps in its own plan. The gateway invokes them. That is the whole difference.
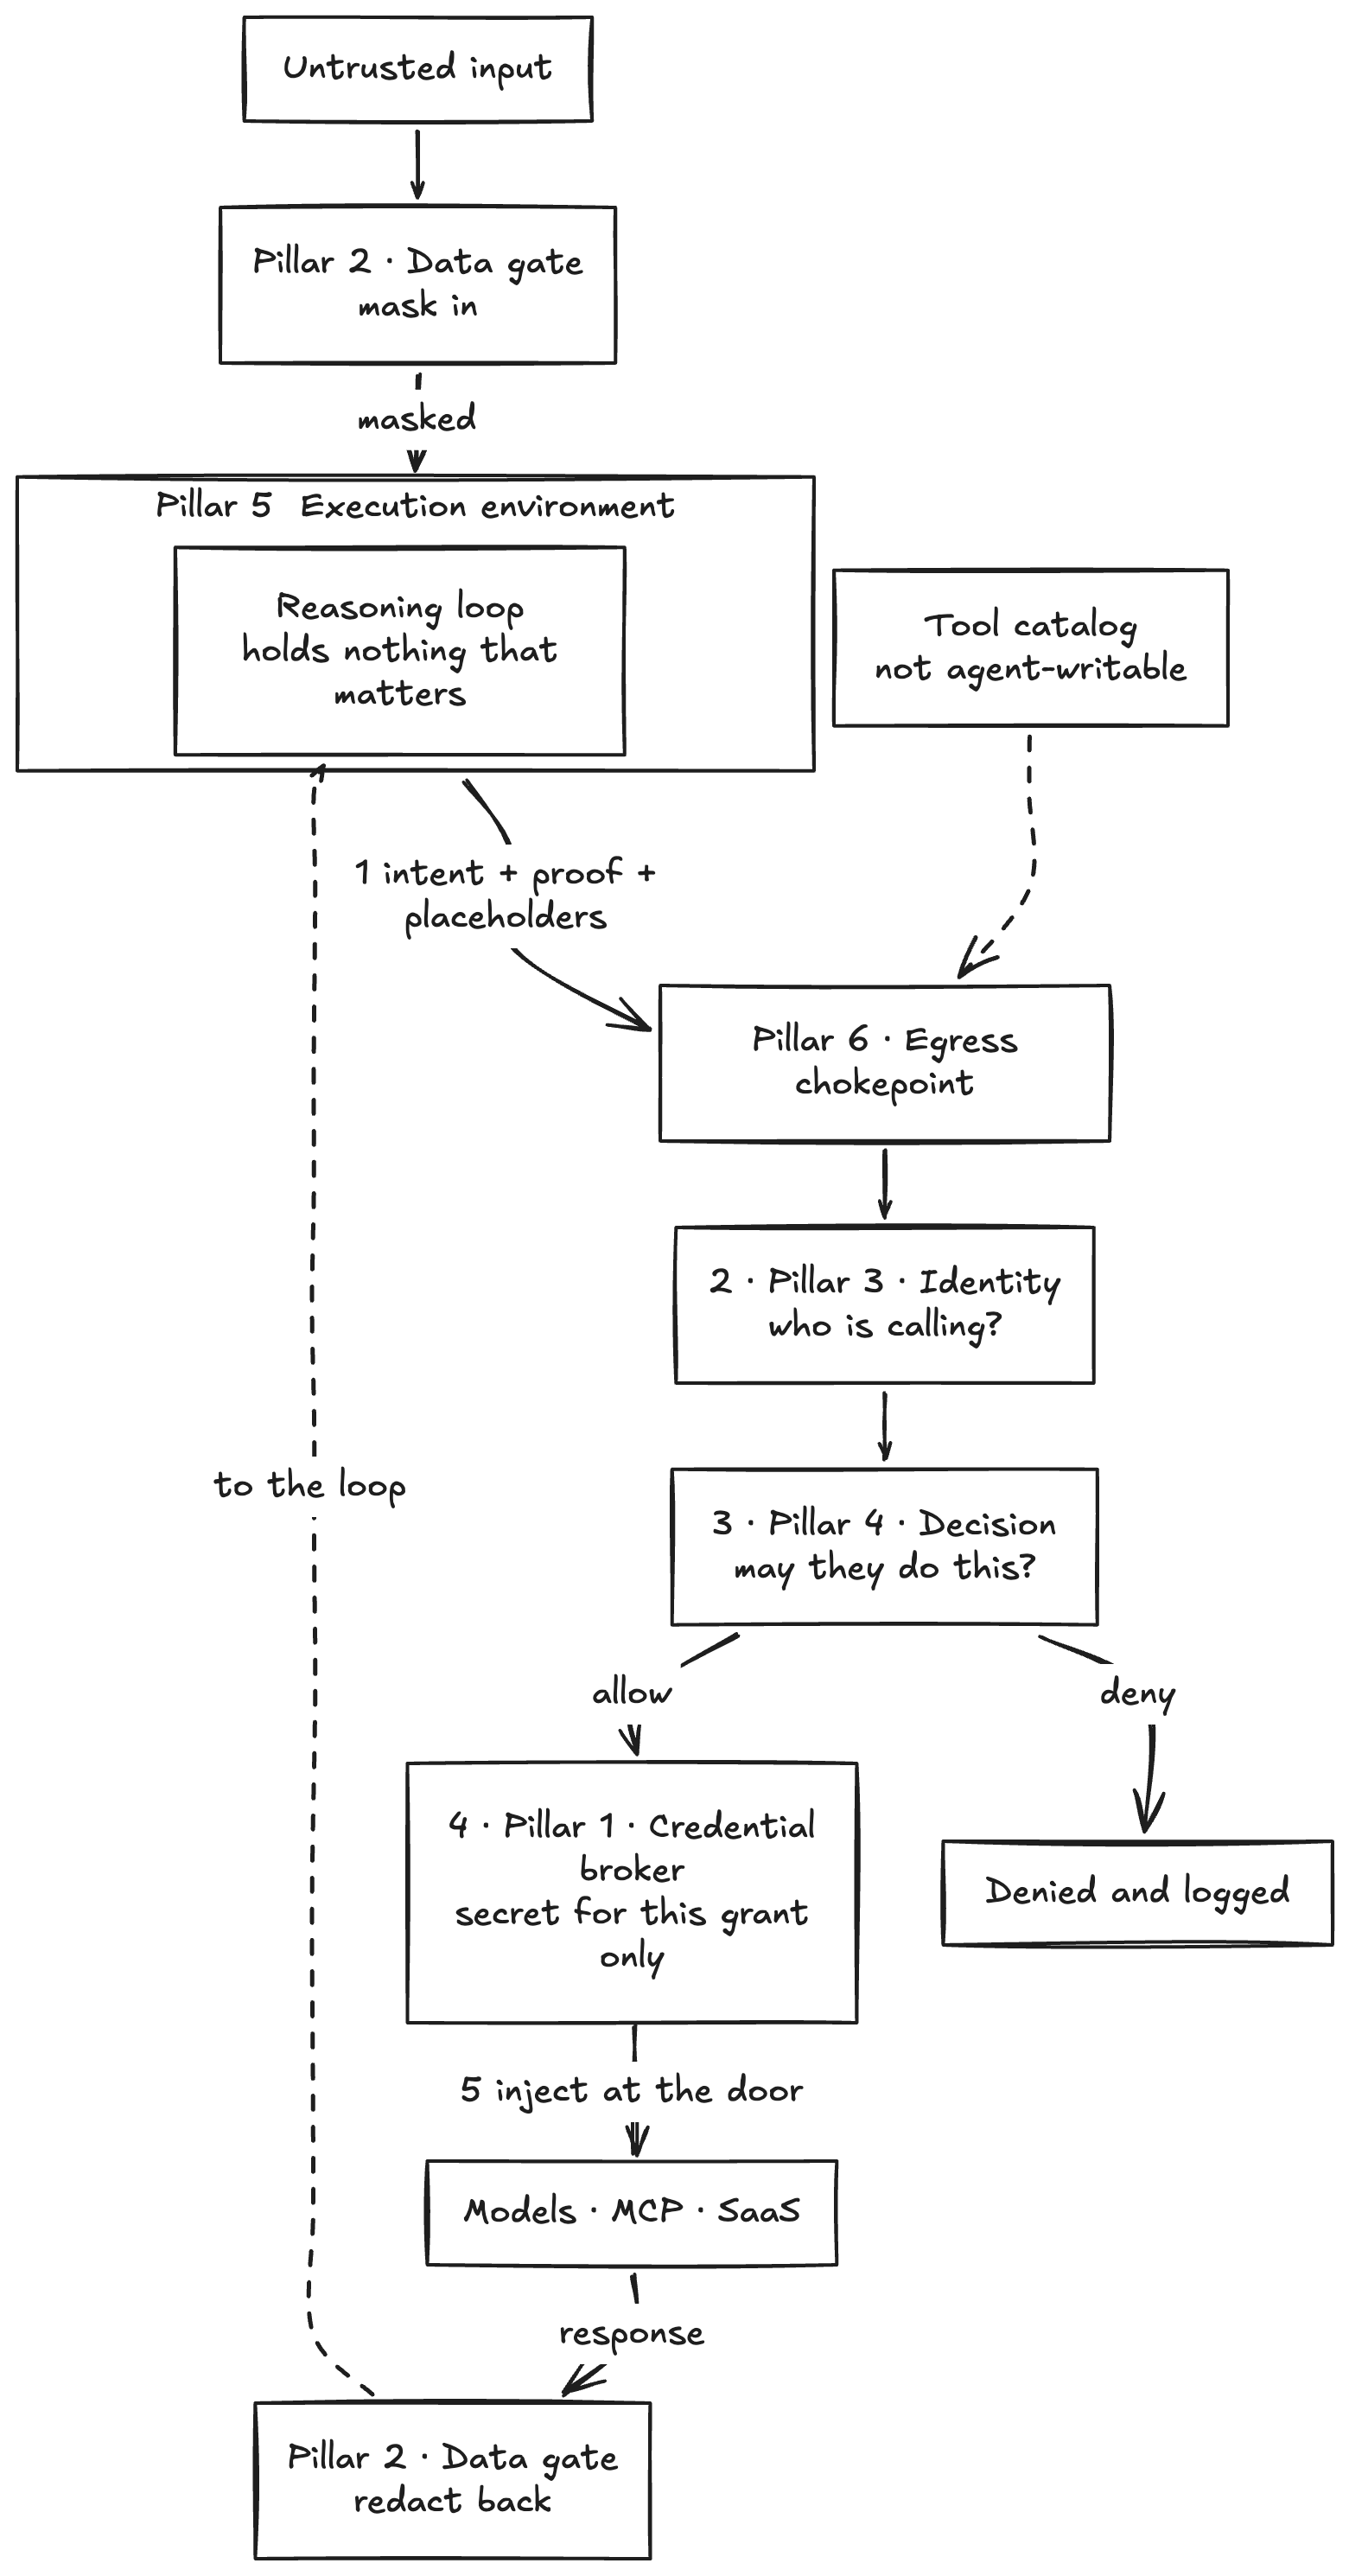
Pillar 3, identity. Who is calling? The identity plane (IdP for a human, workload attestation for a service) issues a short-lived proof. The agent only presents that proof with its intent. It does not mint or expand who it is. Privilege mapping lives outside the loop.
Pillar 4, decision. May this verified principal call this tool on this resource, for this run? Deny by default. The agent proposes. It does not adjudicate.
Pillar 1, credential. Only after allow does the gateway ask the broker for the GitHub / Zendesk / model secret for that grant. That secret is not identity. It is the key the downstream API demands. Injected at the door. Never returned to the agent.
Pillar 6, reach. Same hop forwards the call. The tool catalog the gateway consulted is not writable by the agent.
Pillar 2, data. On the way back (and on the way in from untrusted sources), the data gate keeps raw values out of the loop or provide least identifying representation. On the way out, the door can re-identify tokens for an authorized downstream.
Pillar 5, sandbox. All of the above assumes the process has no other network path. If it can bypass the door, none of the other pillars matter.
Who, then whether, then with what secret, on the only path out. Identity and credential stay separate blocks on purpose: proving who you are must not hand you the SaaS key, and holding the SaaS key must not be how you prove who you are.
And nothing in this picture asks the agent to behave. That is the test I would run on any agent security design: if a control depends on the agent choosing to respect it, it is not a control. It is a suggestion sitting in a document an attacker can also write into.
Once you see the move
Read them back to back and they are the same instinct six times.
the loop must not hold X. It lives instead in Y because Z
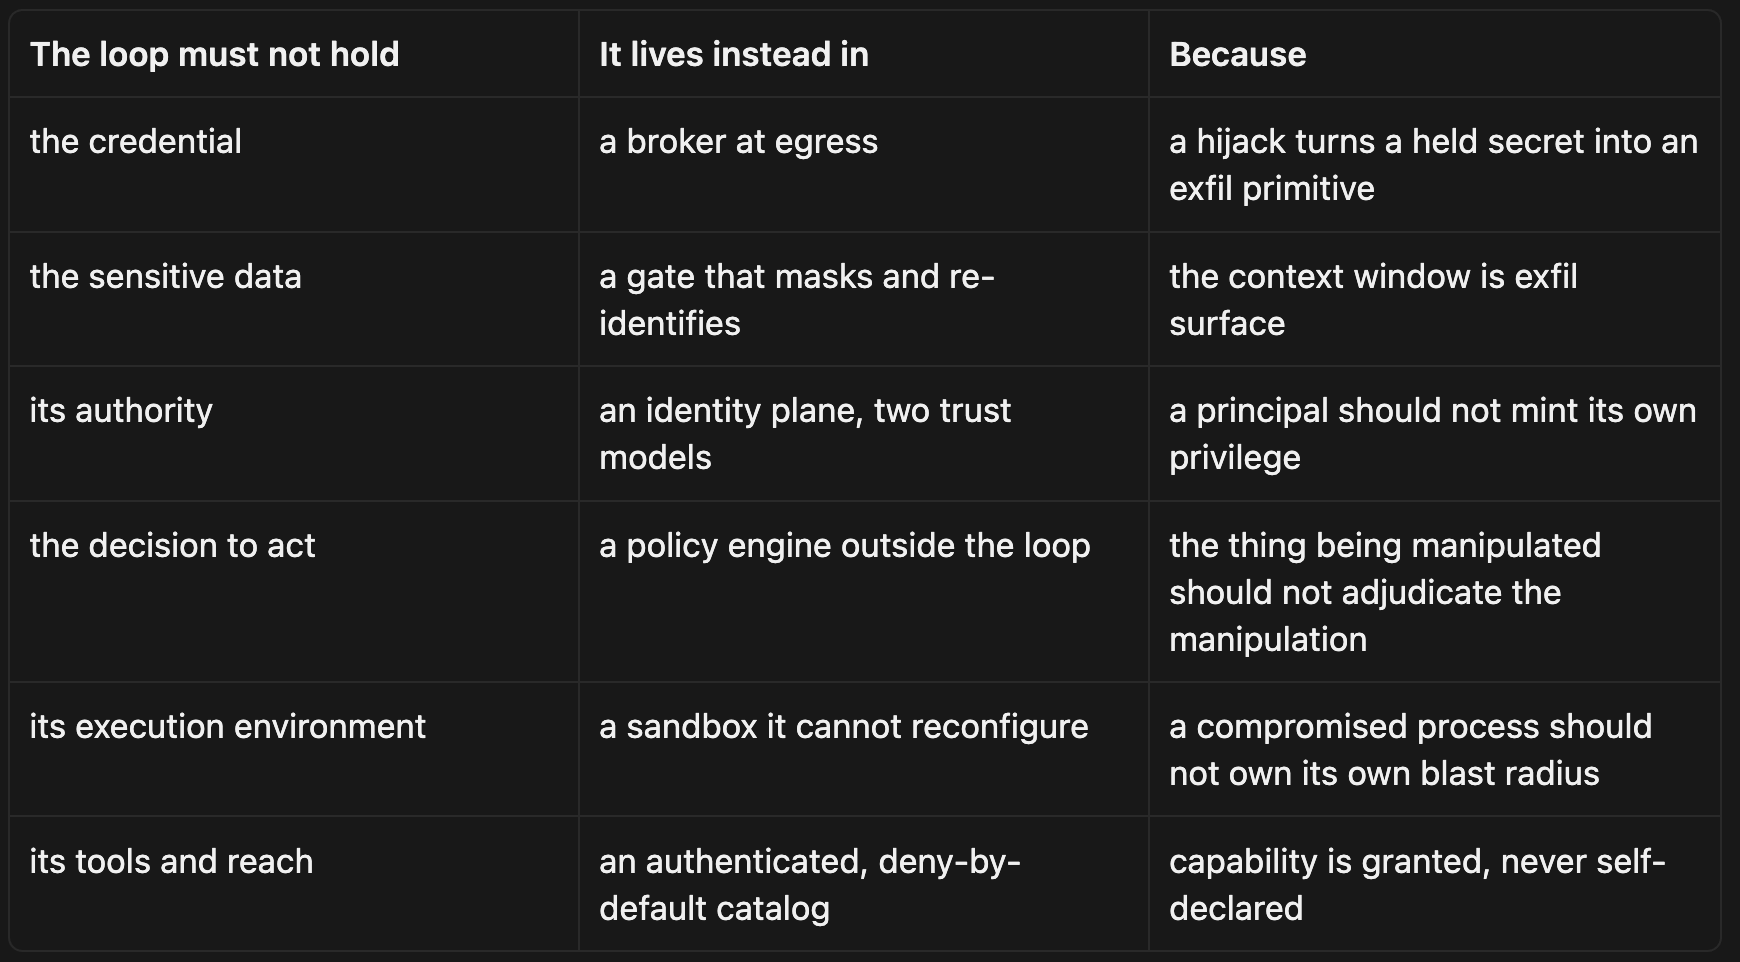
Take it out of the loop’s hands. Hold it somewhere the loop cannot argue with.
Notice what is not on that list: trust the agent. At no point do we ask it to behave. We assume it will not, periodically, inevitably, and put every control where that assumption is survivable.
The Honest Position
I should be clear about what this architecture is not.
It is not free. You have not eliminated custody. You have concentrated it. The broker holds every secret, the gate re-identifies every token, the chokepoint sees every call. The single point of control is also, by construction, the single point of failure and the most attractive target in the estate. That is a deliberate trade: one hardened, monitored, independently-owned place is defensible in a way that a thousand copies scattered across agent environments is not. Make it with your eyes open. Design the chokepoint like the bullseye it is.
And the plumbing is not the hard part. Injecting a secret at egress is solved engineering. Deciding, per request and across a trajectory, whether this agent should call that tool against that resource right now. That is policy. The architecture makes a decision enforceable. It does not make the decision for you.
None of these pillars is exotic. We already did versions of them for services, then quietly stopped when agents arrived. Tokenization took the card number out of the merchant’s hands. The service mesh took auth out of the app. Workload identity killed the static key file. The pillars are those instincts pointed at a principal that reads attacker-influenceable text as input.
Kiro, RufRoot, the OpenAI eval escape: none of them were sophisticated. A config file the agent could write. A bridge nobody authenticated. A test environment holding live credentials. Ordinary defects in front of extraordinary effects. That is exactly what makes them worth building against.
Architecture without an example is only half the post. Next one is the other half: an application built on these pillars, some tools used, what are they good at and tradeoffs.